
In this Article
إن الحاجة إلى تسريع تجريف الويب وتجنب تفعيل أنظمة مكافحة الروبوتات في الوقت نفسه تستدعي أدوات فعالة للتجريف. ويُعد Scrapy من أكثرها استخداماً. تابع القراءة لتعرف لماذا يستحق اهتمامك وكيف تستخدمه بفعالية.
ما هو Scrapy، وما المزايا التي يقدّمها لك؟
Scrapy إطار عمل مفتوح المصدر للزحف على الويب بلغة Python. وتعود شعبيته إلى مزاياه، ومنها:
- القدرة على معالجة طلبات متعددة في الوقت نفسه، مما يجعل تجريف الويب يستغرق وقتاً أقل
- عدم الحاجة إلى صيانة الشفرة البرمجية
- الملاءمة للمشروعات واسعة النطاق
- إتاحة تخصيص معالجة الطلبات والاستجابات، مثل إضافة تدوير وكيل المستخدم، ومعالجة إعادة المحاولات، وإدارة البروكسيات
- يعمل بكفاءة مع مواقع الويب التي تعتمد بكثافة على JavaScript، ويوفر ميزات مثل تأخير الطلب والتقييد التلقائي لتجنب إرهاق الخوادم
- يتضمن مساراً مدمجاً للعناصر، لذا يمكنك استخراج البيانات وتخزينها وحفظها بتنسيقات متعددة، مثل JSON وCSV وXML
- يتضمن محددات CSS وتعبيرات XPath، مما يتيح لك استخراج عناصر HTML المطلوبة بدقة
للتعرف إلى جميع ميزات Scrapy، تفضّل بزيارة الوثائق الرسمية۔ في هذه المقالة، سنركز على كيفية استخدام Scrapy. سنزور مدونتنا ونجرف جميع عناوين المقالات لنوضح لك آلية عمل الأداة.
بما أن تجريف الويب ينطوي على خطر الحظر، فليس جديداً استخدام أدوات الزحف مع البروكسيات. في هذا الدليل، سنوضح لك كيفية تثبيت Scrapy وتخصيصه وكيفية تطبيق البروكسيات.
الاستعداد
قبل البدء، تأكد من توافر جميع البرامج والأدوات اللازمة. نحتاج لهذا الدليل إلى:
- Visual Studio Code أو أي بيئة تطوير متكاملة أخرى تدعم Python
- Python، الإصدار 3.10.0 في حالتنا
- pip، نستخدم الإصدار 25.0.1
يمكنك تنزيل VS Code من هنا وتثبيت Python من الموقع الرسمي۔ إذا لم يكن لديك pip، فهو مُضمّن تلقائياً في Python الإصدار 3.4 والإصدارات الأحدث، فافتح Notebook واحفظ هذه الشفرة في ملف get-pip.py:
import urllib.request
import os
import sys
try:
# download get-pip.py
url = "https://bootstrap.pypa.io/get-pip.py"
urllib.request.urlretrieve(url, "get-pip.py")
# install pip
os.system(f"{sys.executable} get-pip.py")
finally:
# remove the script
if os.path.exists("get-pip.py"):
os.remove("get-pip.py")
بعد ذلك، افتح موجّه الأوامر وانتقل إلى المجلد الذي حفظت فيه الملف:
cd path/to/your/file
على سبيل المثال، حفظنا ملفاً في مجلد Documents، لذا سيبدو أمرنا كالتالي cd/Documents.
بعد ذلك، شغّل الأمر التالي:
python get-pip.py
للتحقق من أن pip يعمل بشكل سليم، استخدم هذا الأمر:
pip --version
والآن، بعد أن أصبح كل شيء جاهزاً، لنبدأ.
تثبيت Scrapy وبدء مشروع
أولاً، نحتاج إلى تثبيت Scrapy. للقيام بذلك، افتح موجّه الأوامر، أو الطرفية في VS Code، وشغّل الأمر التالي:
pip install Scrapy
ملاحظة: إذا ثبّتَّ جميع الأدوات اللازمة لكنك ما زلت ترى رسالة تفيد بأن pip غير معروف كاسم لأمر cmdlet أو دالة أو ملف برنامج نصي أو برنامج قابل للتشغيل، أو ظهرت أخطاء أخرى في طرفية VS Code، فحاول ضبط إعدادات VS Code. انتقل إلى Terminal>Integrated: Default Profile، ويمكنك كتابة terminal integrated في شريط البحث، ثم غيّر الملف الشخصي الافتراضي إلى موجّه الأوامر وأعد تشغيل VS Code لتفعيل الإعدادات الجديدة.
لبدء مشروع، انتقل إلى مجلد مشروعك في طرفية VS Code. في حالتنا، يُسمى المجلد Project S ويوجد في مجلد Documents، لذا نكتب cd Documents/Project S.
ثم اكتب هذا الأمر:
scrapy startproject your_project_name
احرص على استبدال your_project_name باسم فعلي. على سبيل المثال، نستخدم dataimpulse_blog.
بعد ذلك، انتقل إلى مجلد المشروع:
cd your_project_name
عند الوصول إليه، استخدم هذا الأمر لإنشاء عنكبوت زحف:
scrapy genspider your_spider_name url_domain
في حالتنا، يبدو الأمر كالتالي scrapy genspider blog_titles dataimpulse.com
تعديل الشفرة البرمجية
سواء فتحت مجلد مشروعك في VS Code أو عبر مستكشف الملفات، فستجد عدة ملفات Python. نحتاج إلى تعديلها لتجريف البيانات المطلوبة.
أولاً، في مجلد “spiders”، افتح blog_titles.py واستبدل شفرته الحالية بما يلي:
import scrapy
class BlogTitlesSpider(scrapy.Spider):
name = 'blog_titles'
allowed_domains = ['dataimpulse.com']
start_urls = ['https://dataimpulse.com/blog/']
def parse(self, response):
self.logger.info(f"Visited {response.url}")
titles = response.css('h3.blog-title a::text').getall()
for title in titles:
yield {'title': title.strip()}
next_page = response.css('a.next::attr(href)').get()
if next_page:
yield response.follow(next_page, callback=self.parse)
هنا، تحدد الصفحة التي تريد تجريفها والبيانات التي تريد جمعها، وهي العناوين في هذه الحالة. كما تعدّل طريقة parse.
بعد ذلك، افتح middlewares.py والصق الجزء التالي من الشفرة هناك:
# Define here the models for your spider middleware
#
# See documentation in:
# https://docs.scrapy.org/en/latest/topics/spider-middleware.html
from scrapy import signals
# useful for handling different item types with a single interface
from itemadapter import is_item, ItemAdapter
class BlogscraperSpiderMiddleware:
# Not all methods need to be defined. If a method is not defined,
# scrapy acts as if the spider middleware does not modify the
# passed objects.
@classmethod
def from_crawler(cls, crawler):
# This method is used by Scrapy to create your spiders.
s = cls()
crawler.signals.connect(s.spider_opened, signal=signals.spider_opened)
return s
def process_spider_input(self, response, spider):
# Called for each response that goes through the spider
# middleware and into the spider.
# Should return None or raise an exception.
return None
def process_spider_output(self, response, result, spider):
# Called with the results returned from the Spider, after
# it has processed the response.
# Must return an iterable of Request, or item objects.
for i in result:
yield i
def process_spider_exception(self, response, exception, spider):
# Called when a spider or process_spider_input() method
# (from other spider middleware) raises an exception.
# Should return either None or an iterable of Request or item objects.
pass
def process_start_requests(self, start_requests, spider):
# Called with the start requests of the spider, and works
# similarly to the process_spider_output() method, except
# that it doesn’t have a response associated.
# Must return only requests (not items).
for r in start_requests:
yield r
def spider_opened(self, spider):
spider.logger.info("Spider opened: %s" % spider.name)
class BlogscraperDownloaderMiddleware:
# Not all methods need to be defined. If a method is not defined,
# scrapy acts as if the downloader middleware does not modify the
# passed objects.
@classmethod
def from_crawler(cls, crawler):
# This method is used by Scrapy to create your spiders.
s = cls()
crawler.signals.connect(s.spider_opened, signal=signals.spider_opened)
return s
def process_request(self, request, spider):
# Called for each request that goes through the downloader
# middleware.
# Must either:
# - return None: continue processing this request
# - or return a Response object
# - or return a Request object
# - or raise IgnoreRequest: process_exception() methods of
# installed downloader middleware will be called
request.meta['proxy'] = spider.settings.get('http://login:password@hostname:port')
def process_response(self, request, response, spider):
# Called with the response returned from the downloader.
# Must either;
# - return a Response object
# - return a Request object
# - or raise IgnoreRequest
return response
def process_exception(self, request, exception, spider):
# Called when a download handler or a process_request()
# (from other downloader middleware) raises an exception.
# Must either:
# - return None: continue processing this exception
# - return a Response object: stops process_exception() chain
# - return a Request object: stops process_exception() chain
pass
def spider_opened(self, spider):
spider.logger.info("Spider opened: %s" % spider.name)
انتبه إلى السطر 81. هنا، عليك إدخال بيانات اعتمادك الفعلية بتنسيق http://login:password@hostname:port۔ للحصول عليها، انتقل إلى خطة البروكسي المناسبة في لوحة تحكم DataImpulse. لا تنسَ تغيير تنسيق البروكسي من الزاوية السفلية اليمنى. وإذا واجهتك صعوبات، فلا تتردد في الاستعانة بـ دليل إدارة حسابك في DataImpulse.
أخيراً، انتقل إلى settings.py وتأكد من أنه يبدو كالتالي:
# Scrapy settings for blogscraper project
#
# For simplicity, this file contains only settings considered important or
# commonly used. You can find more settings consulting the documentation:
#
# https://docs.scrapy.org/en/latest/topics/settings.html
# https://docs.scrapy.org/en/latest/topics/downloader-middleware.html
# https://docs.scrapy.org/en/latest/topics/spider-middleware.html
BOT_NAME = "dataimpulse_blog"
SPIDER_MODULES = ["dataimpulse_blog.spiders"]
NEWSPIDER_MODULE = "dataimpulse_blog.spiders"
# Crawl responsibly by identifying yourself (and your website) on the user-agent
#USER_AGENT = "blogscraper (+http://www.yourdomain.com)"
# Obey robots.txt rules
ROBOTSTXT_OBEY = True
# Enable the downloader middlewares
DOWNLOADER_MIDDLEWARES = {
'scrapy.downloadermiddlewares.httpproxy.HttpProxyMiddleware': 110,
'scrapy.downloadermiddlewares.useragent.UserAgentMiddleware': None,
'dataimpulse_blog.middlewares.BlogscraperSpiderMiddleware': 543, # Add your ProxyMiddleware here
}
# Configure maximum concurrent requests performed by Scrapy (default: 16)
#CONCURRENT_REQUESTS = 32
# Configure a delay for requests for the same website (default: 0)
# See https://docs.scrapy.org/en/latest/topics/settings.html#download-delay
# See also autothrottle settings and docs
#DOWNLOAD_DELAY = 3
# The download delay setting will honor only one of:
#CONCURRENT_REQUESTS_PER_DOMAIN = 16
#CONCURRENT_REQUESTS_PER_IP = 16
# Disable cookies (enabled by default)
#COOKIES_ENABLED = False
# Disable Telnet Console (enabled by default)
#TELNETCONSOLE_ENABLED = False
# Override the default request headers:
#DEFAULT_REQUEST_HEADERS = {
# "Accept": "text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8",
# "Accept-Language": "en",
#}
# Enable or disable spider middlewares
# See https://docs.scrapy.org/en/latest/topics/spider-middleware.html
#SPIDER_MIDDLEWARES = {
# "blogscraper.middlewares.BlogscraperSpiderMiddleware": 543,
#}
# Enable or disable downloader middlewares
# See https://docs.scrapy.org/en/latest/topics/downloader-middleware.html
#DOWNLOADER_MIDDLEWARES = {
# "blogscraper.middlewares.BlogscraperDownloaderMiddleware": 543,
#}
# Enable or disable extensions
# See https://docs.scrapy.org/en/latest/topics/extensions.html
#EXTENSIONS = {
# "scrapy.extensions.telnet.TelnetConsole": None,
#}
# Configure item pipelines
# See https://docs.scrapy.org/en/latest/topics/item-pipeline.html
#ITEM_PIPELINES = {
# "blogscraper.pipelines.BlogscraperPipeline": 300,
#}
# Enable and configure the AutoThrottle extension (disabled by default)
# See https://docs.scrapy.org/en/latest/topics/autothrottle.html
#AUTOTHROTTLE_ENABLED = True
# The initial download delay
#AUTOTHROTTLE_START_DELAY = 5
# The maximum download delay to be set in case of high latencies
#AUTOTHROTTLE_MAX_DELAY = 60
# The average number of requests Scrapy should be sending in parallel to
# each remote server
#AUTOTHROTTLE_TARGET_CONCURRENCY = 1.0
# Enable showing throttling stats for every response received:
#AUTOTHROTTLE_DEBUG = False
# Enable and configure HTTP caching (disabled by default)
# See https://docs.scrapy.org/en/latest/topics/downloader-middleware.html#httpcache-middleware-settings
#HTTPCACHE_ENABLED = True
#HTTPCACHE_EXPIRATION_SECS = 0
#HTTPCACHE_DIR = "httpcache"
#HTTPCACHE_IGNORE_HTTP_CODES = []
#HTTPCACHE_STORAGE = "scrapy.extensions.httpcache.FilesystemCacheStorage"
# Set settings whose default value is deprecated to a future-proof value
REQUEST_FINGERPRINTER_IMPLEMENTATION = "2.7"
TWISTED_REACTOR = "twisted.internet.asyncioreactor.AsyncioSelectorReactor"
FEED_EXPORT_ENCODING = "utf-8"
هنا، تفعّل البرمجيات الوسيطة وتضبط معلمات أخرى مثل التخزين المؤقت وملفات تعريف الارتباط والمسارات وغيرها.
والآن، نصل إلى أهم خطوة. افتح الطرفية واكتب cd للتأكد من أنك في الدليل الجذر لمشروعك، dataimpulse_blog في حالتنا، إذ عليك البحث عن مجلد يحتوي على ملف scrapy.cfg، وهو الدليل الجذر. ثم استخدم الأمر التالي:
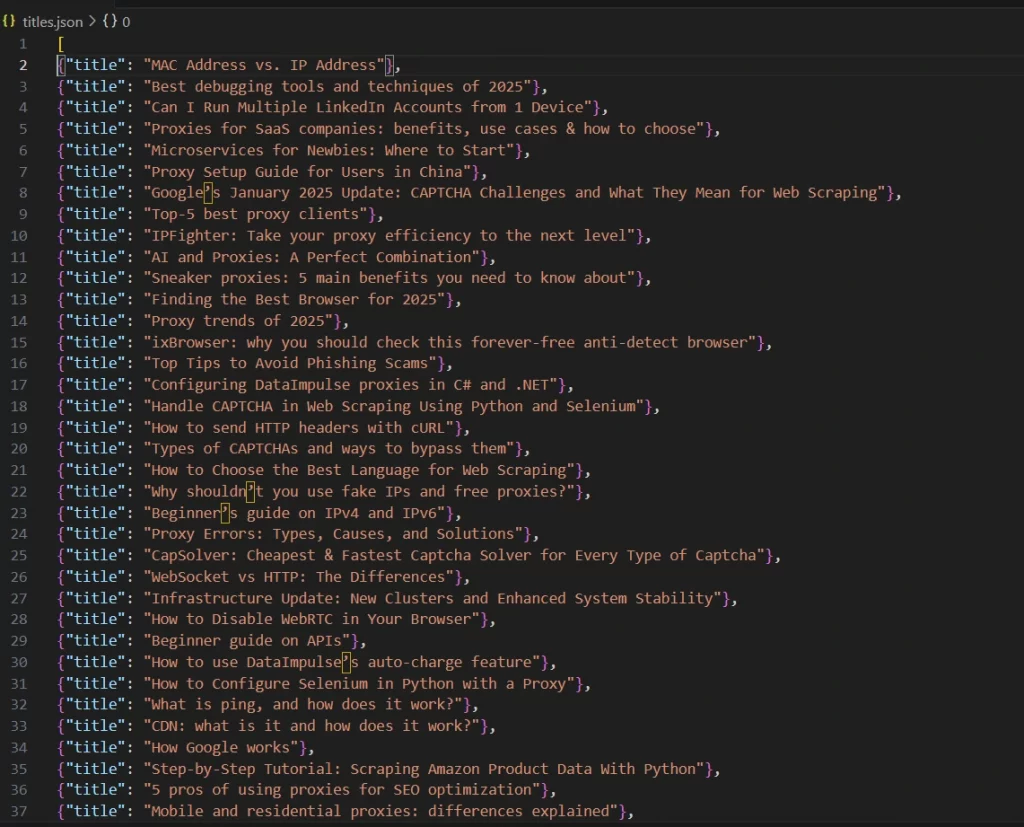
scrapy crawl blog_titles -o titles.json
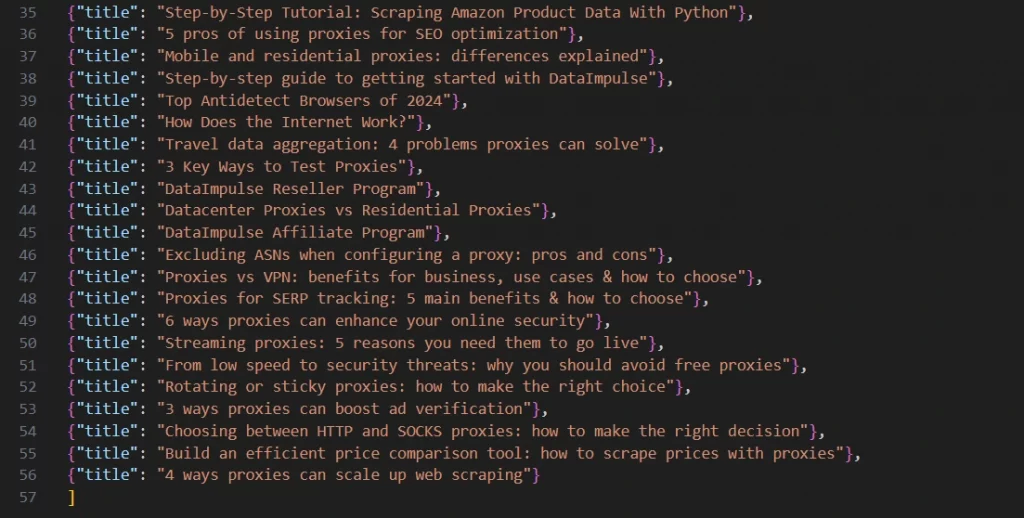
سيشغّل عنكبوت الزحف ويحفظ جميع النتائج في ملف باسم titles.json۔ يمكنك التحقق من النتائج بفتح الملف مباشرة في VS Code. وهذه هي النتيجة التي حصلنا عليها:
والآن انتهيت! كما ترى، استخدام Scrapy سهل. يمكنك ضبط التفاصيل اللازمة والاستفادة من البروكسيات لتحقيق أفضل النتائج. وبالطبع، اختيار البروكسيات مهم أيضاً. تقدم لك DataImpulse بروكسيات سكنية ومن مراكز البيانات ومحمولة، مستمدة بطرق قانونية وبنموذج تسعير الدفع حسب الاستخدام. ولديك عناوين IP مدرجة في القائمة البيضاء لتلبية الاحتياجات العامة من دون استنزاف ميزانيتك. ابدأ معنا بالنقر على زر “جرّبه الآن” أو بمراسلتنا على [email protected].