
In this Article
economics z LLM trening shifted w 2025-2026: Reddit signed AI licensing deals z Google ($60M/yr) i OpenAI ($70M/yr); Stack Overflow + Cloudflare launched pay-per-crawl w February 2026; coalition z 1,500+ wydawców backs Really Simple Licensing (RSL) protocol; Reddit sued Anthropic i Perplexity dla bez licencji web scraping. w same time, dwa federal judges – w Bartz v Anthropic (June 23, 2025) i Kadrey v Meta (June 25, 2025) – independently ruled które trening na publicznych danych jest “highly transformative” i protected under dozwolony użytek. wynik: ML zespoły w 2026 są aggressively collecting publiczne dane z sieci w unprecedented skalę – Common Crawl alone teraz spans 2B+ strony i hundreds z terabytes – ale they’re doing to through residential proxy proxy infrastructure, not naked datacenter IPs, ponieważ wydawca pushback jest rzeczywiste i limity żądań across AI-relevant źródeł have hardened. Whether you’re supplementing Common Crawl z vertical corpora, building wielojęzyczne RAG indexes, assembling image-text pairs dla diffusion trening, lub constructing synthetic-data potoki które query competitors, właściwe proxy stack jest what makes zbieranie potok skalę bez burning IPs.
ten przewodnik ranks 8 najlepsze proxy dla AI i ML dane treningowe zbieranie w 2026, sorts out residential proxy vs datacenter vs mobile vs ISP dla ML potoki, covers zgodne z prawem landscape post-Bartz/Kadrey, i walks through pełne recenzje. Jump do szybkie porównanie dla thirty-second shortlist; deeper zasięg follows.
Kluczowe fakty
ML/AI dane treningowe zbieranie jest jego own proxy market ponieważ zgodne z prawem regime crystallized w 2025-2026, wydawca gatekeeping jest intensifying, i dataset volumes have grown dwa orders z magnitude w trzy lat. pięć things do know up front:
- Public-web trening jest dozwolony użytek; ToS-and-bot-protection jest rzeczywiste gate. Bartz v Anthropic (June 23, 2025, Judge Alsup) ruled trening używać itself “exceedingly transformative” i uczciwe – though Anthropic’s separate downloading z ~7M pirated books dla jego permanent library was NOT dozwolony użytek. Kadrey v Meta (June 25, 2025, Judge Chhabria) ruled w Meta’s favor na developed rekord ale explicitly cautioned które to does NOT stand jako broad authority dla AI trening legality – “te plaintiffs made wrong arguments.” Individual site ToS i bot ochrona (Cloudflare, Akamai, PerimeterX) nadal control practical dostęp. zgodne z prawem coast jest clearer; technical coast jest harder.
- publishing layer jest monetizing. Reddit signed AI licensing deals z Google (~$60M/yr) i OpenAI (~$70M/yr), i jest teraz most-cited źródło w AI models – 3× więcej frequently niż Wikipedia. Reddit sued Anthropic (June 2025) i Perplexity (October 2025) dla bez licencji web scraping. Stack Overflow + Cloudflare launched pay-per-crawl (Feb 2026). RSL (Really Simple Licensing, Sep 2025) gives 1,500+ wydawców machine-readable licencja terms.
- Common Crawl jest bedrock; derivative datasets dominate. Common Crawl ships miesięcznie sieci archiwa spanning ~2B strony i hundreds z TB. C4 (750 GB, Google), RefinedWeb (600B tokens, Falcon), i RedPajama-V2 (100T tokens, 84 miesięcznie CC snapshots 2014-2023) wszystkie derive od to. ML zespoły supplement CC z vertical/wielojęzyczne scrapes – które supplementation jest gdzie proxy enter.
- NYT v OpenAI raised discovery bar. w January 2026, SDNY sąd compelled OpenAI do produce wszystkie 20M ChatGPT logs (not hand-picked subset) do NYT plaintiffs. Production-grade ML potoki należy teraz assume eventual discovery: keep web scraping logs, robots.txt-respect rekordy, i licencja dokumentacja. proxy provider zgodność posture (ISO 27001, SOC 2, ethically-sourced IPs) matters dla audyt trail.
- datacenter IPs flag fast na AI-relevant źródeł. Reddit, Stack Overflow, wiadomości sites (NYT, WSJ, Atlantic), GitHub Codespaces, i major aggregators wszystkie run tier-1 antybotowa stacks. residential proxy i ISP-residential są default dla production AI dane treningowe zbieranie. wskaźnik limity cluster around 1-10 RPS per IP na protected źródeł – Twoje proxy pula size sets Twoje zbieranie throughput.
Jak my Selected te ML Trening Dane Proxy
my picked te 8 providers ponieważ one have credible large-scale residential proxy IP zasięg (ML potoki burn through pools fast), publicznych pricing jako z May 2026, i jeden lub więcej documented features które matter dla AI trening zbieranie – multi-region geo dla wielojęzyczne corpora, sticky sesja długie enough dla paginated archiwum crawls, ISP-residential dla source-licensee konta (Reddit Pushshift, GitHub, Stack Exchange API), per-record zarządzane APIs które handle antybotowa generically, lub ethically-sourced pools które document IP provenance dla legal-audit trail. my weighed live PAYG residential proxy cena per GB, transparency z pricing, freshness z marketing claims, i ranking na independent ML/AI web scraping benchmarks. Providers bez verifiable globalny zasięg, z stale pricing, lub z no publicznych success-rate disclosure were cut.
Co Makes Good proxy dla ML Trening Dane?
strong ML-training proxy stack solves four problems w once. Pula depth w kraj granularity – ML potoki burn through 10–500GB/miesiąc z residential proxy IPs per scraper; pools under 30M IPs exhaust fast i degrade jakość. Multi-region zasięg (US/EU/Asia/LatAm) jest gating dla wielojęzyczne trening corpora i culturally-diverse datasets. Ethically-sourced dokumentacja – post-Reddit-suing-Anthropic i Stack Overflow’s pay-per-crawl, ML zespoły need IP-provenance dokumentacja dla legal-audit trail. ISO 27001 / SOC 2 zgodność jest increasingly procurement-required. PAYG z no expiry – ML danych zbieranie jest spiky: dataset-version-bump cycles, eval-data refresh, vertical-corpus assembly. Subscription lock-in burns budget na idle months. Per-record zarządzane scraper APIs – dla zespoły które don’t want do build i maintain custom parsers against Cloudflare/Akamai, per-record zarządzane APIs (Bright Data, Oxylabs) shift bot-protection problem do proxy vendor. Pick surowe proxy dla wewnętrzne parser zespoły; pick zarządzane APIs dla produkt/research zespoły.
szybkie porównanie: Najlepsze Proxy dla ML & AI Trening Dane w Glance
| Provider | Najlepsze dla | residential proxy cena | Pula | Geo | Notable |
|---|---|---|---|---|---|
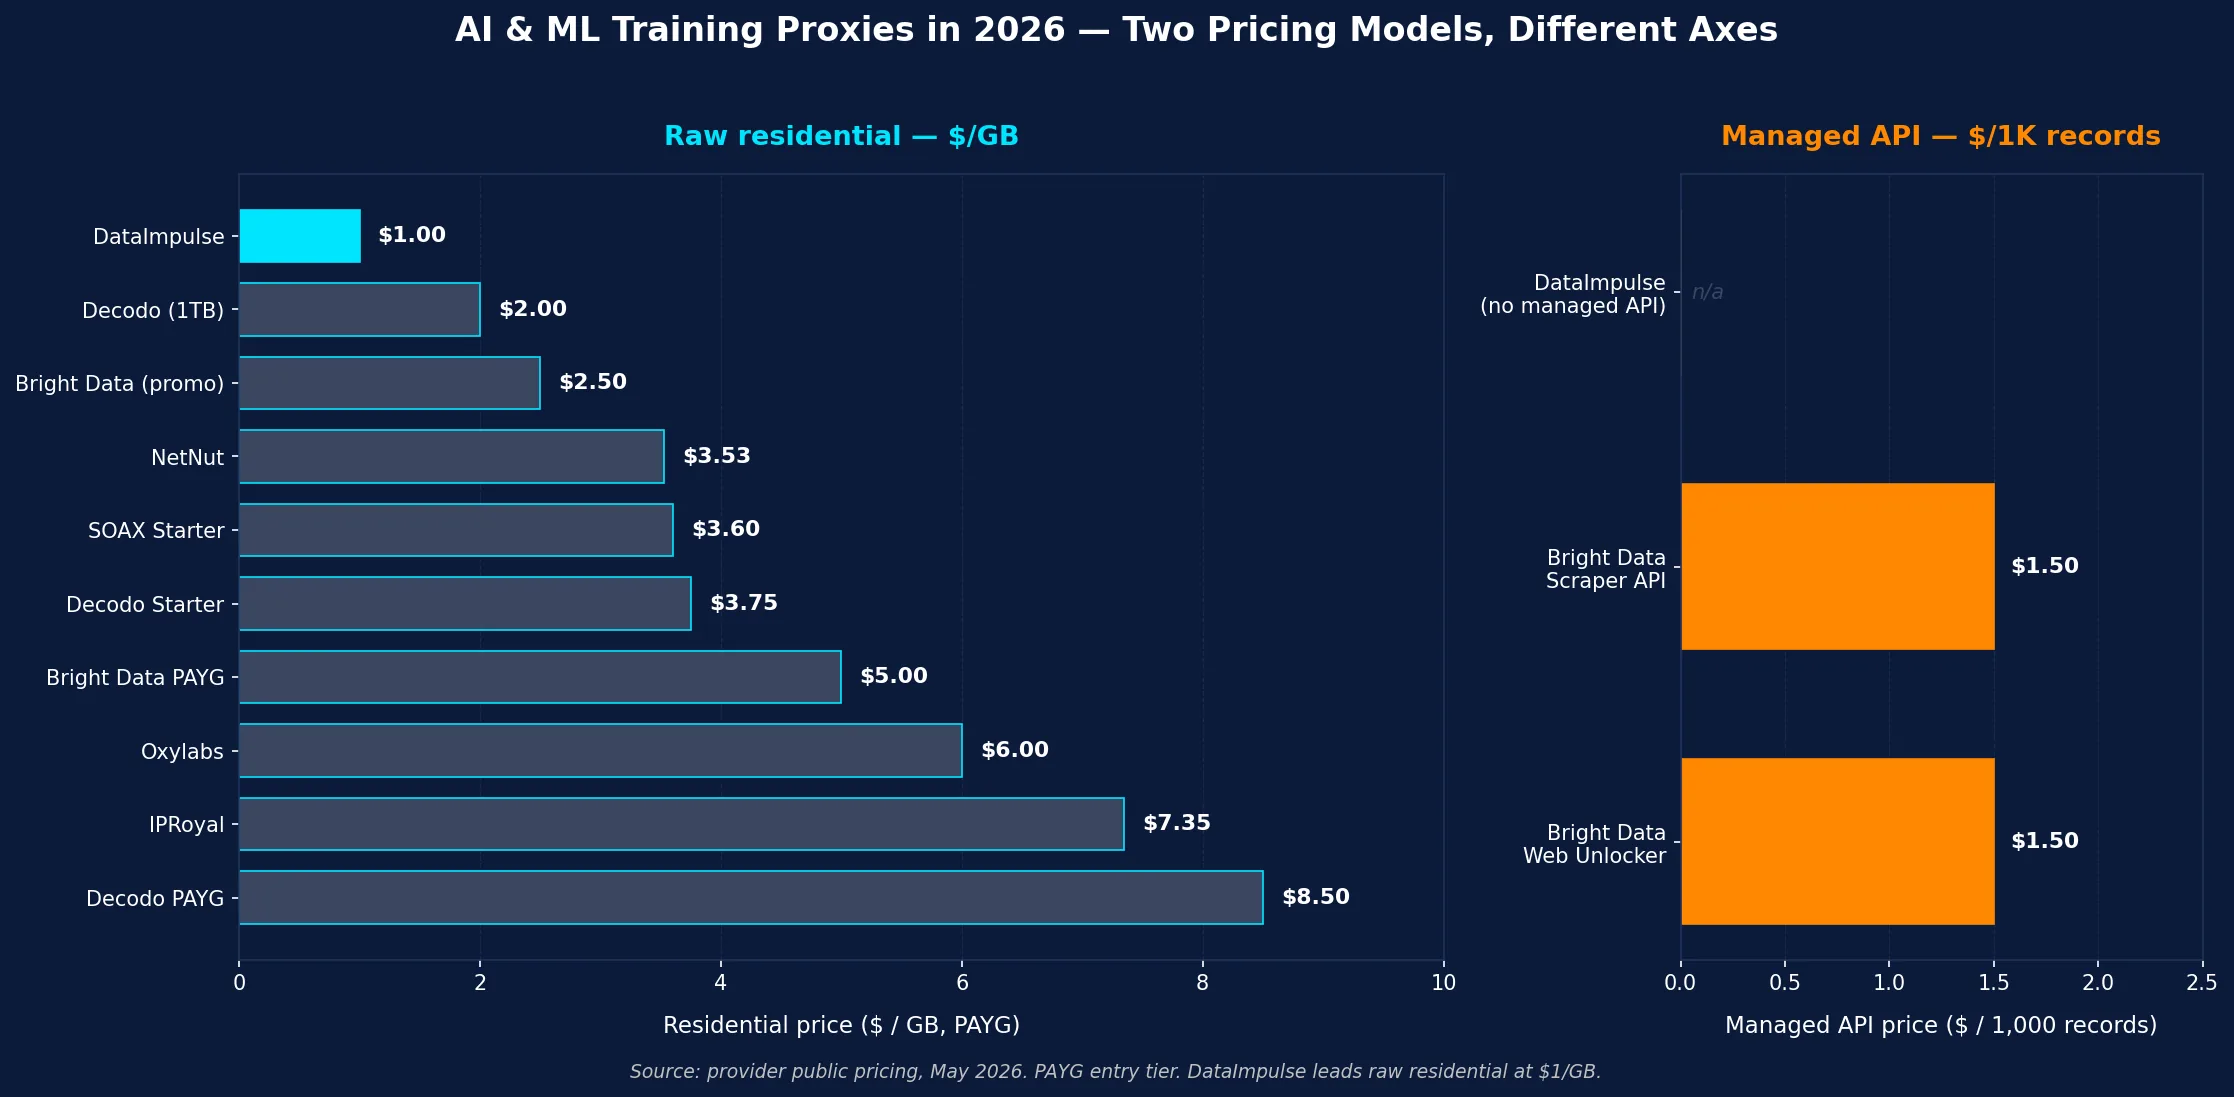
| DataImpulse | Najlepsze value, wewnętrzne ML potoki | $1/GB PAYG | 90M+ residential proxy, 195+ krajów | kraj bezpłatne; stan/miasto/ZIP/ASN 2× wskaźnik | etycznie pozyskane; ruch nigdy wygasa |
| Bright Data | zarządzane Scraper APIs dla AI | ~$4/GB (50% promo); $8/GB regular | 400M+ residential proxy | kraj/miasto/ZIP/ASN bezpłatne | Dedicated Reddit / Stack Overflow / wiadomości Scraper APIs |
| Oxylabs | SLA-grade korporacyjny ML programs | od $6/GB | 175M+ residential proxy | kraj/stan/miasto/ZIP/ASN/coords | Sieć Scraper API; 99.95% sukces |
| Decodo | Mid-market, wielojęzyczne corpora | $3.75/GB starter, $8.50/GB PAYG | 115M+ residential proxy | kraj/miasto/ZIP/ASN wliczone | 195+ locations dla wielojęzyczne sweeps |
| IPRoyal | Long-running trening potoki | od $7.35/GB | 32M+ residential proxy | kraj/region/miasto/ISP | Sticky up do 7 dni |
| SOAX | Mixed proxy types | $3.60/GB Starter | 155M+ res, 33M+ mobile, 2.6M+ ISP | kraj/region/miasto/ISP/ASN | Unified credit; mobile zasięg dla app-based AI |
| Webshare | Cheap Common Crawl supplementation | od $3.50/mo res; $2.99/mo DC | 80M+ residential proxy (sub) | kraj, plan-dependent miasto | Budget pick dla low-defense AI źródeł |
| NetNut | ISP-residential dla czyste dane treningowe | od $3.53/GB | ISP-grade residential proxy | kraj (miasto na wyższe plans) | Consumer-ISP IPs (less noisy niż DC) |
Którego proxy Typ należy Ty Używaj dla ML Trening Dane Zbieranie?
ML dane treningowe zbieranie behaves differently od one-off web scraping work ponieważ volumes są wyższe (10× do 1000× typical price-tracking jobs), freshness requirements są looser (danych ingested once per trening run), i legal-audit trail matters więcej (IP provenance dla fair-use dokumentacja). proxy typu decides Twoje wskaźnik powodzenia i Twoje audyt posture.
residential proxy proxy
residential proxy proxy są właściwe default dla nearly wszystkie serious ML dane treningowe zbieranie – Reddit, Stack Overflow, GitHub Codespaces, wiadomości aggregators (NYT, WSJ, FT, Atlantic, Politico), Wikipedia mirrors i language editions, academic wydawców (Cambridge, Springer, JSTOR public-domain), Medium i Substack newsletters, blog ecosystems, vertical content (zgodne z prawem databases like CourtListener, medical pre-print servers like medRxiv, financial filings like SEC EDGAR publicznych layer), forum i discussion sites, i długie tail z low-traffic specialist sites. rzeczywiste consumer-ISP IPs read jako ordinary readers do bot defense, i świeże globalny residential proxy pula routinely clears Cloudflare’s bot-management layer gdzie datacenter ranges flag w hundreds z requests.
ISP / statyczne residential proxy proxy
ISP proxy (statyczne residential proxy) są właściwe choice dla ML workflows które need sesja continuity lub persistent identity – signed-in Reddit / Pushshift API consumers, Stack Exchange API quota konta, GitHub authenticated crawls, płatne wydawca konta (Bloomberg Terminal feeds, FT subscriptions), i long-running paginated archiwum crawls z wiadomości archiwa lub forum histories. ISP IPs sit na ISP-assigned consumer addresses z stability z statyczne hosting: residential proxy trust z predictability z fixed address. Decodo, IPRoyal, Bright Data, i NetNut wszystkie offer ISP produkt lines.
proxy mobile
mobile proxy route through rzeczywiste carrier networks (Verizon, T-Mobile, w&T, Vivo, Vodafone, Jio, etc.) i earn their place w ML dane treningowe zbieranie dla trzy cases: (1) mobile-first źródeł (Instagram, TikTok gdzie they’re legally accessible, mobile-app forums like Discord publicznych channels) gdzie mobile IPs są native; (2) app-API endpoints które gate harder na non-mobile IPs (Snapchat publicznych, some mobile-version site APIs); (3) hardest antybotowa źródeł (Reddit’s mobile defense, Twitter/X) gdzie rotacyjne mobile IPs są last unblocked lane. mobile jest większość expensive option per GB, so reserve dla jobs gdzie mobile context genuinely matters.
proxy datacenter
datacenter proxy have narrow ale rzeczywiste role w ML dane treningowe zbieranie: bulk crawling z low-defense publicznych źródeł – Common Crawl surowe dostęp (it’s publicznych CDN), publicznych government datasets (danych.gov, EU otwarte Dane Portal, danych.gov.w), otwarte academic repositories (arXiv, PubMed Central), GitHub publicznych repos via v3 API, otwarte Wikipedia dumps, Project Gutenberg, i Hugging Face dataset mirrors. Don’t lean na datacenter dla Reddit, Stack Overflow, wiadomości sites, lub any źródło z serious antybotowa – te flag datacenter ranges within hundreds z requests. Reserve datacenter dla low-defense layer z ML stack, i switch do residential proxy lub ISP jako soon jako target starts challenging Ty.
rotacyjne vs Sticky dla ML Trening Dane
rule dla ML danych zbieranie: rotuj aggressively dla breadth, stick tylko dla paginated context. rotacyjne residential proxy handles broad Common Crawl supplementation, Reddit subreddit-level pulls, Stack Overflow tag-level pulls, news-site full-archive sweeps, i forum-history-by-thread crawls. Sticky sesje handle deeper flows – paginated wiadomości archiwa gdzie Ty need do follow “next strona” links across 50+ strony z same fingerprint, Stack Exchange threaded discussions, multi-page Reddit thread expansions, i any flow gdzie server-side stan needs IP continuity. większość production ML stacks default 90% rotacyjne + 10% sticky dla paginated edge-cases.
Najlepsze Proxy dla ML & AI Trening Dane – pełne recenzje
picks below są ranked na value dla ML dane treningowe zbieranie – balance z pula depth, geo zasięg, antybotowa wskaźnik powodzenia, ethically-sourced dokumentacja, sticky-session length, i cena per successful rekord. DataImpulse leads na value; rest each win specific lane.
1. DataImpulse
DataImpulse jest best-value pick dla wewnętrzne ML zespoły running their own training-data scrapers – Reddit supplementation, Stack Overflow corpus assembly, news-archive harvesting, blog/Medium/Substack crawling, wielojęzyczne Wikipedia mirroring across 195+ locales, GitHub-adjacent code-doc sites, i vertical corpus assembly (zgodne z prawem, medical, financial). residential proxy starts w $1/GB, płatność zgodnie z użyciem, z ruch które nigdy wygasa – fraction z what korporacyjny AI-data scrapers charge, which matters kiedy ML danych zbieranie runs w 100GB-to-multi-TB spikes around dataset-version-bump cycles. pula jest 90M+ etycznie pozyskane IPs across 195 krajów – meaningful dla wielojęzyczne trening corpora gdzie regional IP authenticity decides whether danych reads jako Brazilian-Portuguese lub English-translated-pt. kraj targeting jest wliczone z stan/miasto/ZIP/ASN jako płatne add-on (2× per-GB wskaźnik), useful dla regional-news dane treningowesets i culturally-specific corpora. to supports HTTP, HTTPS, i SOCKS5, rotacyjne i sticky sesja, pełne API dostęp, i standard web scraping stacks (Scrapy, Selenium, Playwright). mobile jest dostępne w $2/GB dla hardest antybotowa AI źródeł; datacenter w $0.50/GB dla public-data layers (Common Crawl mirrors, otwarte government danych, arXiv, publicznych APIs).
Co makes to default dla serious ML danych zbieranie jest price-to-pool-depth ratio combined z etyczne sourcing dokumentacja. w $1/GB Ty can run continuous wielojęzyczne sieci supplementation dla under $1K/TB, i PAYG model means experimenting z new training-data źródeł doesn’t lock Ty into subscription. ethically-sourced 90M pula gives Ty IP-provenance dokumentacja post-Bartz/Kadrey legal-audit trails increasingly want. wsparcie jest 24/7 human; published wskaźnik powodzenia jest 99.51%; G2 jest 4.8/5. There’s no dedicated AI-data endpoint here – DataImpulse sells proxy infrastructure cleanly i lets Twoje ML zespół build scraper layer na top, paired z TLS-fingerprint-aware client (curl_cffi, undetected-chromedriver, Playwright + stealth) dla tier-1 antybotowa AI źródeł.
Najważniejsze parametry – Types: residential proxy, mobile, datacenter · Pula: 90M+ residential proxy, 195 krajów, etycznie pozyskane · rotacja: rotacyjne + sticky · Geo: kraj (stan/miasto/ZIP/ASN jako płatne add-on w 2× wskaźnik) · Cena: $1/GB res, $0.50/GB DC, $2/GB mobile · Published sukces: 99.51% · Rating: G2 4.8.
Najlepsze dla: wewnętrzne ML/AI zespoły które want low płatność zgodnie z użyciem pricing i audit-defensible IP sourcing bez korporacyjny commitments.
2. Bright Data
Bright Data jest korporacyjny pick if Ty want ML dane treningowe jako zarządzane produkt. Beyond surowe residential proxy w $8/GB płatność zgodnie z użyciem (currently discounted do ~$4/GB z 50% promo; deeper $2.50/GB wskaźnik dostępne na $1,999/mo high-volume tier) z 400M+ miesięcznie IP pula i bezpłatne miasto/ZIP/ASN targeting, Bright Data ships dedicated Scraper APIs dla Reddit, Stack Overflow, major wiadomości sites, social platforms, i search-engine SERPs w $1.50 per 1,000 rekordy na PAYG (about $1.30/1K na $499 plan). Sieć Unlocker w $1.50/1K wyniki handles arbitrary AI-relevant źródeł generically – point to w Cloudflare-protected blogs, Akamai-fronted wiadomości archiwa, lub PerimeterX-defended forums i to returns rendered HTML. ISO 27001, SOC 2 Typ II, documented privacy-law zgodność (RODO/CCPA/LGPD-aligned), i audit-ready dokumentacja clear większość korporacyjny procurement i większość ML legal-risk recenzje. It’s właściwe call kiedy you’d rather hit zarządzane Reddit lub NYT endpoint niż maintain parser against publisher-side rate-limit i DOM churn – w korporacyjny pricing z procurement-style buying.
Najważniejsze parametry – Types: residential proxy, DC, ISP, mobile + dedicated Reddit/Stack-Overflow/wiadomości/social Scraper APIs + Sieć Unlocker · Pula: 400M+ miesięcznie residential proxy · rotacja: rotacyjne, sticky, dedicated · Geo: kraj/miasto/ZIP/ASN bezpłatne · Cena: ~$4/GB res (promo); $8/GB regular (deeper $2.50/GB na $1,999/mo high-volume tier); Scraper APIs od $1.50/1K rekordy PAYG (~$1.30/1K na $499 plan); subscription od $499/miesiąc · zgodność: ISO 27001, SOC 2 Typ II.
Najlepsze dla: korporacyjny ML/AI danych zespoły które want zarządzane Scraper APIs dla Reddit/SO/wiadomości z audit-ready zgodność i SLA controls.
3. Oxylabs
Oxylabs sits next do Bright Data w korporacyjny top z deep ML-training zasięg. residential proxy starts around $6/GB na entry plan z 175M+ pula across 195 krajów i strong geo zasięg z miasto, stan, ZIP, ASN, i geographical coordinate targeting (essential dla region-specific trening corpora). Sieć Scraper API ($49/miesiąc entry) handles JavaScript rendering, antybotowa bypass, i structured danych extraction across AI-relevant źródeł including Reddit, wiadomości sites, i SERPs. sesje są flexible z unlimited concurrent connections (matters dla ML potoki które fan out do 1000+ concurrent scrapers during dataset-collection sprints), i Oxylabs publishes 99.95% residential proxy wskaźnik powodzenia. Pick Oxylabs kiedy niezawodność, SLA-grade wsparcie, ISO 27001 / SOC 2 zgodność, i procurement-grade dokumentacja matter więcej niż entry cena – particularly dla korporacyjny ML programs które need procurement docs dla legal-risk recenzje na training-data provenance.
Najważniejsze parametry – Types: residential proxy, DC, ISP, mobile + Sieć Scraper API · Pula: 175M+ residential proxy, 195 krajów · rotacja: flexible, sticky, unlimited concurrency · Geo: kraj/stan/miasto/ZIP/coordinates/ASN · Cena: od $6/GB residential proxy; Sieć Scraper API od $49/miesiąc · Published sukces: 99.95% · zgodność: ISO 27001, SOC 2.
Najlepsze dla: korporacyjny ML programs które want SLA-grade zarządzane web scraping z ISO 27001 / SOC 2 zgodność i concurrent-fanout wsparcie.
4. Decodo
Decodo (formerly Smartproxy) jest mid-market sweet spot dla ML dane treningowe work – especially wielojęzyczne corpora. residential proxy proxy zacznij w $3.75/GB na 3 GB starter plan z PAYG w $8.50/GB na publicznych pricing strona, dropping do about $2/GB w 1,000 GB tier. kraj, miasto, ZIP, i ASN targeting są wliczone z 115M+ IPs across 195+ locations – meaningful dla ML zespoły building wielojęzyczne datasets które need authentic regional IPs (Wikipedia language editions, regional wiadomości archiwa, country-specific forums). statyczne residential proxy/ISP starts w $0.27/IP – jeden z większość aggressive ISP limity dla static-residential workflows like Reddit Pushshift-style konta, Stack Exchange API quota konta, i Common Crawl supplementation runs które span weeks. Sieć Web scraping API includes templates dla major content źródeł, z sticky sesja up do 24 hours.
Najważniejsze parametry – Types: residential proxy, DC, ISP, mobile + Sieć Web scraping API · Pula: 115M+ residential proxy, 195+ krajów · rotacja: per-request, sticky up do 24h · Geo: kraj/miasto/ZIP/ASN wliczone · Cena: $3.75/GB starter, $8.50/GB PAYG, $2/GB w 1TB+; statyczne residential proxy/ISP od $0.27/IP · Published sukces: 99.86%.
Najlepsze dla: mid-market ML zespoły building wielojęzyczne trening corpora lub running długie static-residential ML konta.
5. IPRoyal
IPRoyal earns jego spot dla long-running ML trening potoki – multi-day Common Crawl supplementation sweeps, multi-page paginated news-archive crawls, persistent Reddit account-tied scrapes, long-running forum-history harvests gdzie sesja continuity over dni matters. residential proxy PAYG runs $7.35/GB w entry (cheaper w volume) z 32M+ pula across 195+ krajów z kraj, region, miasto, i ISP targeting. jego rzeczywiste differentiator jest sticky sesja up do 7 dni, longest na ten list – uniquely useful dla multi-day ML data-collection sprints gdzie rotacyjne sesje break paginated server-state, Reddit/SO API-key-tied konta gdzie sesja continuity jest gating, i long-running training-data assembly potoki. There’s również ISP produkt line i Sieć Unblocker (CAPTCHA + antybotowa bypass) w per-request pricing.
Najważniejsze parametry – Types: residential proxy, ISP, mobile, DC + Sieć Unblocker · Pula: 32M+ residential proxy, 195+ krajów · rotacja: rotacyjne, sticky up do 7 dni · Geo: kraj/region/miasto/ISP · Cena: od $7.35/GB residential proxy PAYG.
Najlepsze dla: multi-day ML data-collection potoki które need sticky-session continuity across paginated archiwa.
6. SOAX
SOAX jest pick kiedy mixed proxy types matter dla ML potok. residential proxy starts w $3.60/GB na Starter plan (25 GB wliczone), i unified credit model means Ty can spend same budget na residential proxy, mobile, ISP, datacenter, lub Sieć Dane API. pula jest jeden z larger w mid-tier – 155M+ residential proxy, 33M+ mobile, 2.6M+ ISP – z kraj, region, miasto, ISP, i ASN targeting. Sticky sesje są supported across wszystkie proxy types. Convenient if Twoje ML potok mixes residential proxy dla broad wiadomości/forum scrapes, mobile dla hardest źródeł (Reddit mobile, TikTok-style platforms), i ISP dla account-tied API consumers (Reddit, Stack Exchange) under jeden subscription z shared credit.
Najważniejsze parametry – Types: residential proxy, mobile, ISP, DC + Sieć Dane API · Pula: 155M+ residential proxy, 33M+ mobile, 2.6M+ ISP · rotacja: per request lub interval, sticky supported · Geo: kraj/region/miasto/ISP/ASN · Cena: $3.60/GB Starter.
Najlepsze dla: ML zespoły running mixed-type zbieranie (residential proxy + mobile + ISP) across jeden subscription.
7. Webshare
Webshare earns jego place dla ML zespoły running cheap large-volume crawling na low-defense AI źródeł – Common Crawl mirror dostęp (it’s publicznych CDN), publicznych open-data repositories (danych.gov, EU otwarte Dane Portal, arXiv, PubMed Central, GitHub publicznych API, HuggingFace dataset mirrors), public-domain text archiwa (Project Gutenberg, Internet archiwum), i low-traffic specialist sites bez serious antybotowa. Plans zacznij w $2.99/miesiąc dla 100-proxy datacenter package i $3.50/miesiąc dla entry rotacyjne residential proxy plan z 80M+ residential proxy dostępne na wyższe tiers, plus statyczne ISP proxy na subscription plans. Webshare residential proxy jest najlepsze na lower-defense ML danych źródeł; dla tier-1 antybotowa (Reddit, NYT, Stack Overflow), step up do providers above.
Najważniejsze parametry – Types: residential proxy, statyczne ISP, datacenter · Pula: 80M+ residential proxy (subscription); datacenter i ISP dostępne · Geo: kraj, plan-dependent miasto · Cena: od $2.99/miesiąc datacenter (100 proxy); rotacyjne residential proxy od $3.50/miesiąc.
Najlepsze dla: ML zespoły running cheap large-volume crawling na publicznych open-data i low-defense AI źródeł.
8. NetNut
NetNut closes list z focus na ISP-residential niezawodność dla ML dane treningowe – czyste consumer-ISP IPs które look less synthetic w audyt trail niż aggressive rotating-residential pools. produkt line emphasizes ISP-grade residential proxy IPs (Comcast, Charter, Vodafone, BT, Deutsche Telekom, i other consumer-ISP-assigned addresses) z rotacyjne i sticky options. rotacyjne residential proxy currently starts around $3.53/GB na entry plans, scaling up przez volume; kraj i city-level targeting dostępne na wyższe tiers. NetNut jest pick kiedy Ty specifically want consumer-ISP-residential network depth dla audit-defensibility lens – IPs read jako ordinary home internet users w any subsequent zgodne z prawem lub audyt scrutiny z training-data źródeł.
Najważniejsze parametry – Types: ISP-residential, residential proxy, mobile · Pula: ISP-grade residential proxy z deep major-ISP zasięg · rotacja: rotacyjne, sticky · Geo: kraj (miasto na wyższe plans) · Cena: od $3.53/GB residential proxy.
Najlepsze dla: ML zespoły które want consumer-ISP-residential IPs dla audit-defensibility z their training-data zbieranie potok.
Jak Much Do ML Trening Dane Proxy Koszt?
Listed pricing w 2026 falls into trzy bands. Budget/value w $1–$3.75/GB – DataImpulse, SOAX Starter, Decodo entry, Webshare residential proxy subscription – covers większość wewnętrzne ML dane treningowe zbieranie. Mid/premium w $3.50–$7.35/GB – Bright Data, Oxylabs, IPRoyal, NetNut – adds korporacyjny tooling, SLA-grade niezawodność, i audit-ready zgodność posture. API-priced i ISP-priced – Bright Data’s Scraper APIs $1.50/1K rekordy PAYG (~$1.30/1K na $499 plan), Oxylabs Sieć Scraper API od $49/mo, Decodo Sieć Web scraping API od $19/mo, Decodo US ISP w $0.27/IP – sell structured outcomes per rekord, per plan, lub per IP instead z per GB.
rzeczywiste koszt question dla ML dane treningowe isn’t “what’s lowest $/GB” ale “what’s lowest koszt per successful, audit-defensible trening rekord”. zarządzane scraper API w $1.30–$1.50/1K rekordy can beat $1/GB residential proxy kiedy Twoje wewnętrzne scraper hits Cloudflare lub Akamai blocks na 30–50% z requests; conversely, $1/GB residential proxy z TLS-fingerprint-aware client i sticky sesja dla paginated archiwa routinely beats per-record APIs w multi-TB skalę once Twoje wewnętrzne parser jest mature. dla ML budgets running 100GB-1TB/week, surowe residential proxy wins na $/rekord; dla smaller research/eval-data needs, zarządzane APIs win na engineering time.
jest to Zgodne z prawem do Używaj Proxy dla ML & AI Trening Dane Zbieranie?
ML dane treningowe prawo sits w intersection z US copyright (fair-use post-Bartz/Kadrey), CFAA (hiQ v LinkedIn), wydawca umowy (Reddit/SO licensing), stan prywatność prawo (CCPA/CPRA + EU RODO), i patchwork z national AI/danych laws (DPDP w India, LGPD w Brazil). basics:
- Trening na publiczne dane z sieci jest dozwolony użytek (US) – z carve-outs. Bartz v Anthropic (June 23, 2025, Judge Alsup) ruled trening itself “exceedingly transformative” i dozwolony użytek under 17 USC §107 – ale downloading ~7M pirated books do build Anthropic’s permanent library was NOT dozwolony użytek, separate-and-significant carve-out. Kadrey v Meta (June 25, 2025, Judge Chhabria) ruled dla Meta na rekord ale explicitly cautioned ruling does not stand jako broad AI-training-is-fair authority. pending Authors Guild v OpenAI i consolidated w re: OpenAI Copyright Infringement Litigation cases will refine boundary. publicznych + transformative + non-substitutionary = dozwolony użytek, z provenance hygiene jest working framework.
- Public-data web scraping jest CFAA-safe. 9th Circuit’s hiQ Labs v LinkedIn (2022) ruling established które web scraping publicly accessible sieci danych does not violate Computer Fraud i Abuse Act. Meta v Bright Data (2024) reinforced ten z public-vs-logged-in distinction: publicznych jest fine; logged-in konto web scraping triggers contract-breach exposure.
- wydawca umowy override fair-use defense dla licencjonowane źródeł. Reddit, Stack Overflow, NYT, WSJ, i 1,500+ RSL-protocol signatories distribute their danych under explicit licensing terms. Web scraping te źródeł dla trening bez licencja triggers contract-breach claims (Reddit v Anthropic 2025, Reddit v Perplexity 2025). fair-use defense doesn’t excuse contract-breach.
- Discovery jest new exposure surface. NYT v OpenAI (January 2026 SDNY ruling): OpenAI was compelled do produce wszystkie 20M ChatGPT logs, not hand-picked subset. Production ML potoki należy assume eventual discovery – keep web scraping logs, robots.txt-respect rekordy, licencja dokumentacja, i proxy-vendor IP-provenance attestations.
- Cross-border prywatność prawo applies do dane osobowe. RODO (EU), CCPA/CPRA (California), LGPD (Brazil), DPDP Act 2023 (India, phased through 2027) wszystkie govern dane treningowesets które contain dane osobowe z residents w those jurisdictions. Web scraping dane osobowe bez zgodne z prawem basis jest enforceable independent z fair-use defense. Strip dane osobowe od trening corpora kiedy possible, document strip step dla audyt.
honest reading: large-scale ML trening na publiczne dane z sieci jest legally defensible w 2026 under Bartz/Kadrey + hiQ, ale contract layer (Reddit, SO, RSL signatories) i personal-data layer (RODO/CCPA/LGPD/DPDP) są rzeczywiste exposure. publicznych/non-licensed/non-dane osobowe jest lowest-risk lane; licensed-source web scraping i personal-data web scraping są highest. Get US copyright + tech-transactions counsel before scaling production ML trening potok. do nie jest porada prawna.
Jak do Zacznij ML Trening Dane Zbieranie z DataImpulse
- Utwórz konto i pick Twoje proxy mix. residential proxy ($1/GB) dla Reddit, Stack Overflow, wiadomości archiwa, forum histories, blog/Substack/Medium scrapes, wielojęzyczne Wikipedia mirrors, i vertical corpora (zgodne z prawem/medical/financial); datacenter ($0.50/GB) dla enrichment layer (Common Crawl mirrors, arXiv, PubMed, GitHub publicznych API, danych.gov, EU otwarte Dane Portal, public-domain archiwa); mobile ($2/GB) dla hardest antybotowa AI źródeł gdzie rotacyjne mobile IPs są last unblocked lane.
- Dodaj funds. Pay-as-you-go, no subscription, no expiry – handy ponieważ ML danych zbieranie runs w 100GB-to-multi-TB spikes around dataset-version-bump cycles, eval-data refresh, i vertical-corpus assembly sprints, then idles dla weeks.
- Zaplanuj dla audyt trail. Set kraj targeting matching Twoje corpus regional balance (US/EU/Asia/LatAm dla wielojęzyczne trening; specific krajów dla regional corpora), choose rotacyjne dla breadth + sticky dla paginated archiwa, point Twoje scraper w proxy endpoint i run. Log every scrape z timestamp, target URL, proxy sesja ID, i robots.txt-respect outcome – ten jest Twoje post-Bartz/Kadrey audyt defense layer.
dla więcej na related workflows, see our residential proxy proxy produkt strona, datacenter proxy produkt strona (dla Common Crawl i open-data layer), najlepsze proxy dla sieci web scraping roundup, i najlepsze proxy dla SEO & rank tracking roundup.
FAQ
jest to zgodne z prawem do używać proxy dla AI dane treningowe zbieranie?
dla publiczne dane z sieci, yes – Bartz v Anthropic (June 23, 2025) i Kadrey v Meta (June 25, 2025) both ruled które trening AI na publiczne dane z sieci jest “highly transformative” i protected przez dozwolony użytek under 17 USC §107. 9th Circuit’s hiQ v LinkedIn (2022) ruling protects underlying web scraping under CFAA. ale wydawca umowy (Reddit, Stack Overflow, RSL-protocol signatories) override dozwolony użytek dla licencjonowane źródeł – Reddit sued Anthropic (June 2025) i Perplexity (October 2025) dla bez licencji web scraping. osobowe danych triggers RODO/CCPA/LGPD/DPDP regardless. Get US copyright + tech-transactions counsel before production. do nie jest porada prawna.
Co proxy do production LLM trening potoki actually używać?
Production ML zespoły typically run tiered stack: datacenter proxy ($0.50/GB) dla public-data layer (Common Crawl, arXiv, GitHub publicznych API, otwarte repositories); residential proxy proxy ($1–$3.75/GB) dla bulk z sieci web scraping (Reddit, Stack Overflow, wiadomości, forums, blogs); mobile proxy ($2–$10/GB) reserved dla hardest antybotowa źródeł (Reddit mobile, social platforms); i zarządzane Scraper APIs ($1.30–$1.50/1K rekordy) kiedy wewnętrzne parsing time jest więcej expensive niż per-record koszt. DataImpulse, Bright Data, i Oxylabs wszystkie show up w production ML stacks.
Jak does Reddit’s pozew against Anthropic affect ML trening zbieranie?
Reddit sued Anthropic w June 2025 dla bez licencji web scraping z Reddit content do train Claude, i sued Perplexity w October 2025 na similar grounds. Reddit-Google i Reddit-OpenAI licensing deals ($60M/yr i $70M/yr respectively) set cena floor dla licencjonowane Reddit danych. Practical implication: if Twoje ML potok scrapes Reddit w skalę, either licencja to (Reddit Dane API) lub accept contract-breach exposure. Public-only-CC-supplementation potoki które include incidental Reddit content via Common Crawl carry materially niższe ryzyko.
Co about web scraping Stack Overflow i Stack Exchange?
Stack Overflow + Cloudflare launched pay-per-crawl w February 2026 – bots są charged w gateway. Stack Exchange API has limity żądań i ToS prohibiting bulk redistribution. dla ML dane treningowe, zgodne z prawem path jest: używać publicznych Stack Exchange API quota (z auth), respect per-IP rate-limits, lub licencja bulk dostęp od Stack Overflow’s korporacyjny zespół. Bypass via residential proxy proxy jest technically possible ale increases contract-breach exposure.
Do I need kraj diversity w my proxy pula dla wielojęzyczne trening?
Tak dla wielojęzyczne trening corpora. ML zespoły building genuinely wielojęzyczne datasets need authentic IPs od language regions – Wikipedia-de scraped via US IPs returns English-redirect lub English-formatted content sometimes; Reddit subreddit pulls od r/Brasil show different sticky posts based na viewer IP geo; regional wiadomości archiwa geo-fence przez visitor kraj. DataImpulse, Decodo, Oxylabs, i Bright Data wszystkie have 195+ kraj zasięg. SOAX i IPRoyal have strong kraj breadth na entry plans.
Jak do I make my dane treningowe zbieranie audit-defensible?
pięć practices: (1) Używaj ethically-sourced proxy pools (DataImpulse, Bright Data, Oxylabs wszystkie publish IP-provenance docs); (2) Log every scrape z timestamp, URL, proxy sesja ID, response code, i robots.txt-respect outcome; (3) Respect robots.txt gdzie to exists; (4) Strip dane osobowe od trening corpora i document strip step; (5) dla licencjonowane źródeł (Reddit, SO, NYT), maintain licencja dokumentacja lub skip them i rely na Common Crawl’s snapshot. Post-NYT-v-OpenAI January 2026 ruling, assume eventual discovery – audyt trail jest no longer optional.
Common Crawl jest bezpłatne – why pay dla proxy w wszystkie?
Common Crawl covers ~2B strony miesięcznie ale lags 1–3 months i skews do high-traffic English-language sites. ML zespoły używać proxy dla: (1) supplementation z fresher danych (recent wiadomości, recent Reddit threads, recent papers); (2) wielojęzyczne zasięg beyond CC’s English bias; (3) vertical corpora (zgodne z prawem, medical, financial, scientific) które CC under-samples; (4) specific źródło completeness (e.g., complete Reddit archiwum vs CC’s sample); (5) personal-data-stripped potoki gdzie Ty need real-time web scraping do apply Twoje own prywatność filters. CC jest bedrock; proxy są augmentation layer.
mobile proxy dla ML – kiedy do one matter?
trzy cases: (1) mobile-first źródeł (Instagram, TikTok public-domain, mobile app forums) gdzie mobile IPs są native; (2) app-API endpoints które gate harder na non-mobile IPs (some mobile-version site APIs, push-notification feeds); (3) hardest antybotowa źródeł gdzie Cloudflare/Akamai/PerimeterX block residential proxy too – mobile carrier IPs są last unblocked lane. SOAX, IPRoyal, DataImpulse, i Bright Data wszystkie offer mobile proxy. Reserve mobile dla jobs gdzie mobile context genuinely matters – one koszt więcej per GB i Twoje ML potok rarely needs pełne mobile premium.
statyczne residential proxy / ISP proxy dla ML – kiedy?
Używaj ISP/static-residential dla ML workflows które need sesja continuity across dni – Reddit Pushshift-style konta które hold paginated archiwum context, Stack Exchange API quota konta, płatne wydawca konta (Bloomberg, FT), long-running multi-day forum history harvests gdzie rotacja breaks server-side pagination stan. Decodo (od $0.27/IP), IPRoyal, NetNut, Bright Data, i Webshare wszystkie sell ISP produkt lines. dla one-off ML danych sprints, rotacyjne residential proxy jest cheaper; dla persistent identity, ISP jest tylko option.
Gotowy do run audit-defensible ML i AI dane treningowe zbieranie w skalę? Zacznij z DataImpulse – residential proxy od $1/GB, datacenter od $0.50/GB, mobile od $2/GB, płatność zgodnie z użyciem z ethically-sourced 90M+ IPs across 195 krajów, kraj targeting wliczone (stan/miasto/ZIP/ASN jako płatne add-on), i ruch które nigdy wygasa.