In this Article
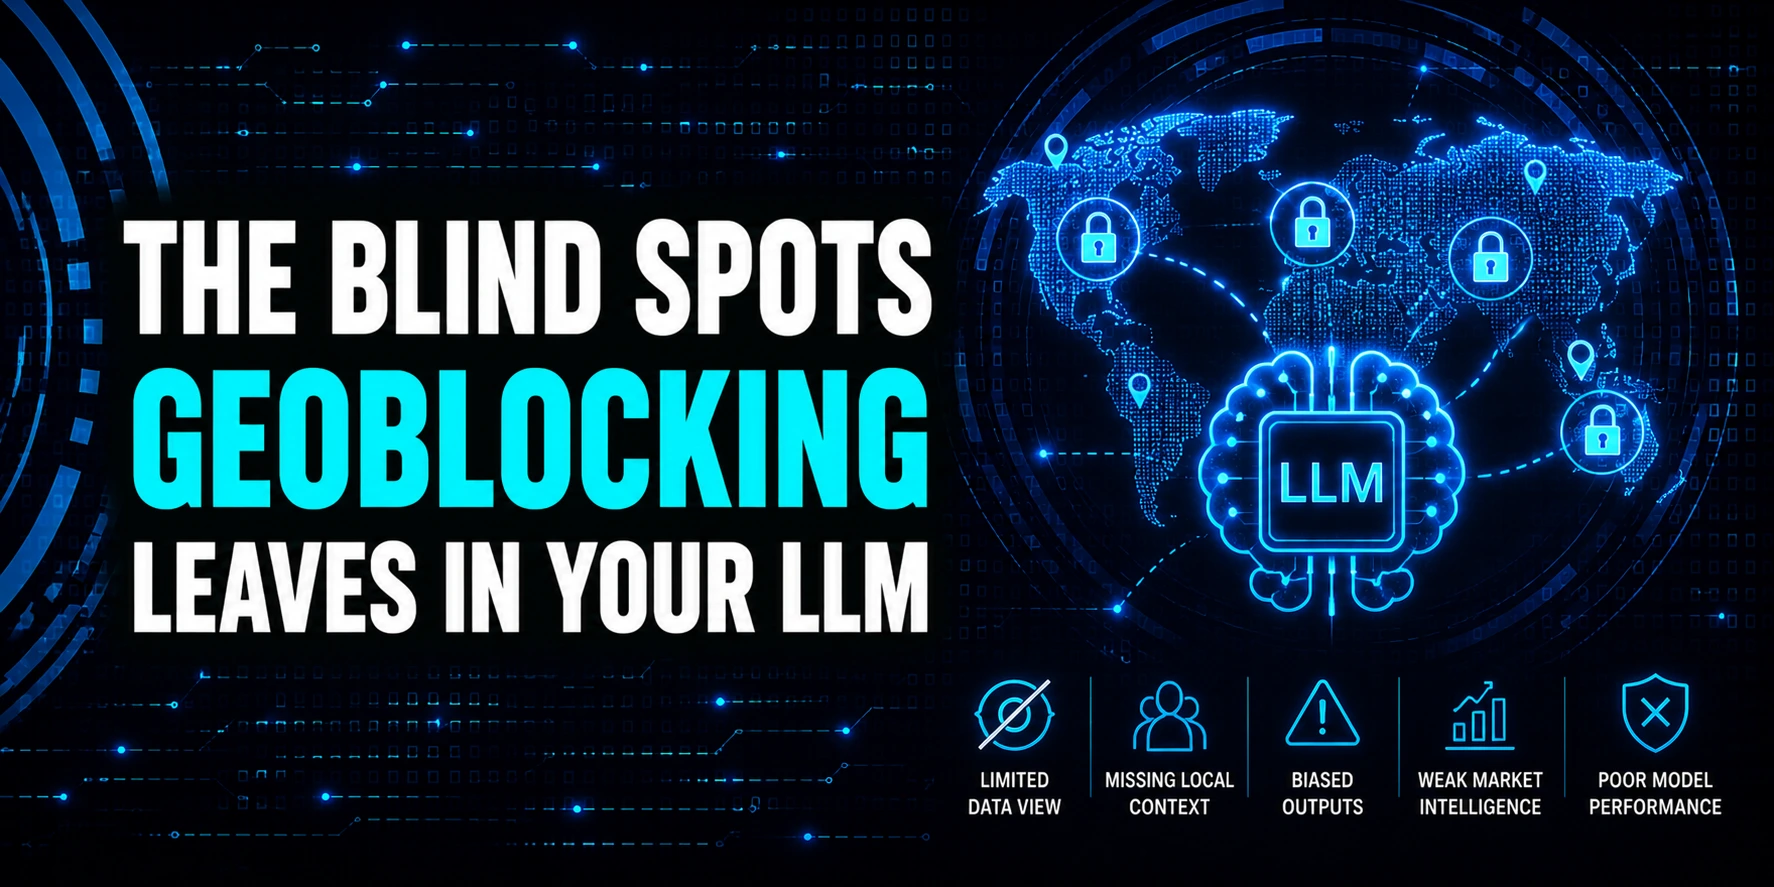
Imagine a situation: your team gathered data to train a multilingual model. The pipeline worked just fine without stumbling upon blocks, and you conducted training. However, some time after you get to the production stage, the research team notices that the model systematically does not understand the location-specific context for Vietnam, Japan, or Korea. This is not because there was no data, but because your crawler never got it, due to geo-related access requirements.
This is not a hypothetical case or out-of-the-ordinary problem – this is a structural challenge the AI industry faces today.
DataImpulse, a proxy provider with 5+ years of experience, knows a thing or two about issues that involve one’s location – and in this article, we share how proxies help get over them.
Key Facts:
- Users from different regions see the Net differently due to content licensing, data laws, and safety issues. So do crawlers.
- Geoblocks are hard to detect as requests are often returned, and it looks like pages do not have anything interesting, not that your crawler was denied. As a result, you get data with blind spots.
- You need to spot such biases and document them, so you can understand the limitations and risks of models trained on such data.
- It is better to have documented biases than to stay clueless regarding gaps in training data. In the first case, regulators see it as having control over your model; in the second case, not knowing would only harm you.
- Proxies can help with ASN/IP level detection – the exact layer where geo-blocks usually work. Though proxies are still only a part, though the essential one, of a scraping infrastructure.
Why does QA not see blind spots in local data?
The thing is that the Internet is not the same for everyone. You may visit the same website, look for the same goods, and get totally different prices, availability, shipping options, etc. This is because of your location. The same happens to your crawler – it gets to see and scrape what is visible in your location.
There are different reasons why that happens. European platforms block requests originating from non-EU IPs due to license restrictions for content and GDPR compliance rules. South-east asian government sources providing open data limit access for traffic originating from non-residential IPs out of “digital sovereignty” concerns. Latin America e-commerce websites show entirely different page versions to crawlers from the USA – not only in terms of local currency or shipping options, but even in product descriptions and availability. Retail websites in Japan and Korea distinguish requests coming from non-native ASNs on the CDN level, even before they reach the origin server.
For a developer who works with scraping without geo-unlocking infrastructure, that will look like the source is impossible to reach. In reality, a great blind spot hides behind that – and it won’t be in any CI/CD report, because technically, your crawler does not encounter an error while scraping, it just can not get data.
Why are geo-related issues in AI training data so serious?
There are three main reasons.
First, high-quality English-language data is running out. According to researchers (Epoch AI, 2024 impact report), with current scaling tendencies, the world may be short of publicly available English text by the end of this decade. This makes AI developers actively explore multilingual corpora. And this is where geo-based filtration is the strictest due to technical reasons – local infrastructure was never designed to support global access.
Second, pressure from regulators on data provenance grows by the day. You may be lost as to how it applies to geo-based restrictions – if you do not get data because of geo-based restrictions, how on Earth could someone ask you to prove its legal origin? However, the EU AI Act and other similar documents require providing not only the data source. If you deal with high-risk industries like healthcare or finance, you must also check whether training data has blind spots or biases and prove that you have evaluated the representativeness of your dataset. It is not enough to show that you have not broken any restrictions – it is about showing that you know what is in your data, what is lacking, and you know about possible limitations and risks your model will have because of those unseen areas. If you do not know about such biases or can not explain why they appeared, it may be seen as not sticking to the requirements.
Also, a model trained on biased data, may perform unfairly or poorly for some region or group of people. In such cases, a regulatory institution would be interested in the people affected, not in what you did while gathering training data. And if your model receives complaints because of discrimination or safety issues, the answer “We got lopsided training data because our crawler was blocked from regional sources” is a poor excuse that won’t save you from reputational damages, fines, or court proceedings. It does not mean that your model absolutely cannot have any weak spots. Again, it is about you being aware of them. Ironically, but admitted and documented blind spot looks like more control over your pipeline and is better for avoiding issues with regulators, than accidental, unrecorded bias, even if accidental mistakes are more sympathetic morally.
Third, if you sell datasets, enterprise clients usually conduct a careful investigation before signing supply contracts. They ask about documentation and whether the data is representative enough. It’s not about law – it is about risk management, because the data you provide directly influences how their models will perform. Datasets representing generic tendencies and stripped of location-specific data are not something in demand, meaning you will also have less profit from selling them. On the contrary, limited-access repositories, local forums, niche-spesific data bases – not abused, domain-specific, low-resource data is a prize any research lab is fighting for now. Whoever gets stable access to such sources first, gets clients, reputation, and income.
What exactly happens with datasets when geo-restrictions are ignored
The main problem with geo-based bias is that they do not look like an error and often show themselves with time, when performance quality lowers. On the training stage, when it is simpler, faster, and cheaper to fix everything, such blind spots stay out of sight.
- Temporal asymmetry. When your crawler cannot get to sources in a particular region, and then suddenly it can (for example, because content licensing requirements change), the model ends up having an artificial gap in topic representation – it thinks that the topic emerged way later than it really happened.
- Skew. Models that are used for purposes like AI-powered predictive campaigns and trained on e-commerce or financial data need location-specific data to understand local trends and tendencies to provide reliable results. Generic training data, true for only some locations, render such models worthless.
- Language barrier. Local content often includes slang, terminology, and spoken variants of words that are often present only on local forums or news aggregators. Content polishing for ad campaigns, instruction tuning, and successfully dealing with local-specific search is impossible without knowing such aspects.
How enterprise proxies can help
First of all, you need to know that access denial does not occur on one level. It may happen on DNS, ASN, CDN levels, or when the platform combines TLS fingerprinting with behavioral signals. In order to prevent it, you need to build an infrastructure – combine several tools that would cover all of those levels. Proxies are one of such tools, but do not expect that proxies will solve all the scraping-related problems. Though truth be told, geo restrictions are proxies’ forte.
However, not all proxies are equally effective when it comes to enterprise scraping.
Datacenter proxies can stay reliable even under the load. They provide room for scaling requests. On the other hand, when you need to access location-specific content, you need ASN diversity – so that the addresses you use belong to various ASNs and your traffic looks authentic. Datacenter proxies cannot offer that. Also, they often belong to the same subnet, further giving away scraping activities and causing access denials. It is better to use them for internal checks or for low-volume scraping on local websites without sophisticated protective measures.
Residential proxies, as well as mobile proxies, are tied to a particular location and allow requests to look like organic traffic from a particular region. ASN reputation of a local user and IP addresses that rotate naturally lead to a high success rate, uptime, and data. Such proxies are also more immune to changes in websites’ anti-bot policies.
The important difference between those types of proxies is price. Datacenter proxies are alluring because they are noticeably cheaper. However, if scraping AI training data is your routine, it is more cost-effective to rely on proxies that won’t require you to constantly retry, adjust the whole pipeline each time anti-bot policies change, or get you unreliable data.
What should you do before scraping data for AI training
There are only three criteria to check your scraping infrastructure against:
- Can we document the origin of data in a dataset for each region – ASN, geolocations?
- If the target website updates its anti-bot policies, will our proxies deal with the million-requests load without drastically losing success rate?
- Are we sure the proxies we use are ethically obtained?
The last part is not a formality either – you need to prove not only data origin is legal, but the tools you use to get data are legal as well.
To sum up
Geo blocks are not just a minor issue. It is an essential part of the Net that only grows more noticeable with market fragmentation and regulatory pressure. Teams that keep geo-restrictions in mind while designing their infrastructure and create a way to get location-specific information are the successful ones, even if they lack in terms of innovations.
Frequently Asked Questions
Can we just detect geoblocking later and re-crawl the necessary sources?
Geoblocks are hard to detect because requests often return some data, which makes it look like a page did not have data, rather than the request was denied. Also, recrawling will not bring you any better results unless you build an infrastructure that can grant you access to location-specific sources. So, such an approach would probably waste your time, leading you to the same answer - reliable infrastructure.
Are geo-related blocks only a problem for multilingual or non-English models?
No, even English-language models have data gaps - especially if data sources serve different content by region across English-speaking markets - obviously, situations and content would be different in Britain and India, though both are English-speaking. It is just that multilingual and non-English models face the problems more often, so it is more visible.
How to understand whether it is a geoblock to blame for a data gap or content is just non-existent?
Try accessing the same URLs using local residential IPs and non-local datacenter IPs. Any difference - content length, HTTP status, or server versions - all indicate that geoblocks are active.
Do residential proxies fully solve geo-blocking issues?
Residential proxies solve ASN/IP-level issues, and such problems are the most common trigger. You can get residential proxies at DataImpulse for $1/GB. On the other hand, residential proxies alone are not enough to deal with TLS fingerprinting, so you will need a strategy for that as well.
What is DataImpulse?
DataImpulse (dataimpulse.com) is an ethical provider of residential, mobile, and datacenter proxies. The vendor also offers premium residential IPs for the most sensitive use cases. The company operates on a pay-as-you-go pricing model, selling non-expiring traffic for web scraping, AI data gathering, ad verification, price monitoring, SERP tracking, and more - all with 24/7 human support.
When not to use DataImpulse?
DataImpulse has some limitations, like no scraping API, no access to government and banking sources, and no ISP proxies. There are also no static proxies.
 State/City/Zip/ASN Targeting